| Age | Commit message (Collapse) | Author |
|---|
|
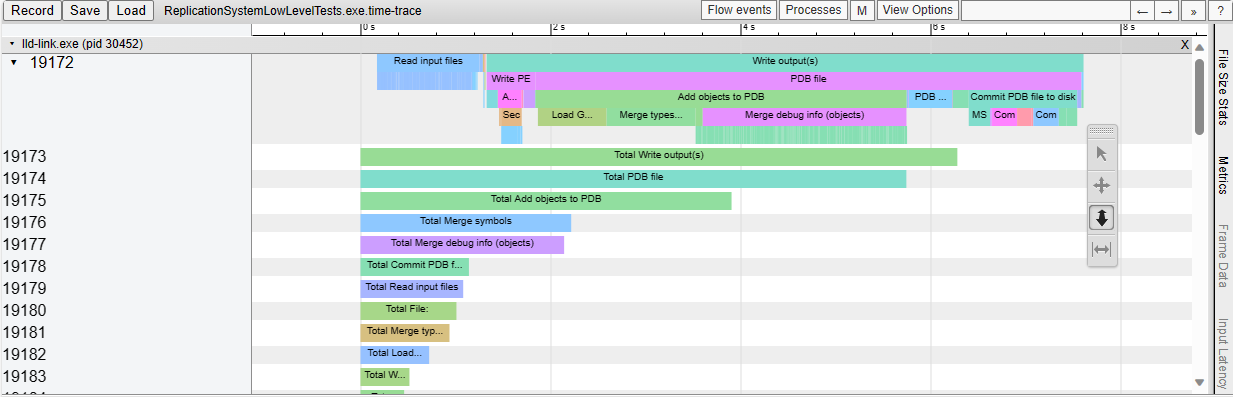
This adds support for generating Chrome-tracing .json profile traces in
the LLD COFF driver.
Also add the necessary time scopes, so that the profile trace shows in
great detail which tasks are executed.
As an example, this is what we see when linking a Unreal Engine
executable:
|
|
Identified with readability-qualified-auto.
|
|
|
|
The construction was explained in
https://reviews.llvm.org/D44810?id=139526#inline-391999 but reading the code
shouldn't require hunting down old reviews to understand it.
The precomputed list was missing an entry for the empty list case, and
one entry at the very end. (The current last entry is the last one where
3 * BucketCount fits in a signed int, but the reference implementation
uses unsigneds as far as I can tell, so there's room for one more entry.)
No behavior change for inputs seen in practice.
Differential Revision: https://reviews.llvm.org/D64738
llvm-svn: 366107
|
|
lld-link used to write PDB files that DIA couldn't recover natvis
files from if:
- The global strings table was > 64kiB
- There were at least 3 natvis files
The cause was that the hash function for the /src/headerblock stream
was incorrect: It needs to be truncated to 16 bit.
If the global strings table was <= 64kiB, truncating to 16 bit is a
no-op, so this wasn't needed for small programs.
If there are only 1 or 2 natvis files, then the growth strategy in
HashTable::grow() would mean the hash table would have 2 buckets (for 1
natvis file) or 4 buckets (for 4 natvis files), and since the hash
function is used modulo number of buckets, and since 2 and 4 divide
0x10000, the missing `% 0x10000` is a no-op there too. For 3 natvis
files, the hash table grows to 6 buckets, which has a factor that's not
common with 0x10000 and the difference starts to matter.
Fixes PR41626.
Differential Revision: https://reviews.llvm.org/D61277
llvm-svn: 359515
|
|
This avoids allocating a few KB of heap memory on startup, and instead
allocates these maps lazily. I noticed this while profiling LLD.
llvm-svn: 357192
|
|
to reflect the new license.
We understand that people may be surprised that we're moving the header
entirely to discuss the new license. We checked this carefully with the
Foundation's lawyer and we believe this is the correct approach.
Essentially, all code in the project is now made available by the LLVM
project under our new license, so you will see that the license headers
include that license only. Some of our contributors have contributed
code under our old license, and accordingly, we have retained a copy of
our old license notice in the top-level files in each project and
repository.
llvm-svn: 351636
|
|
This was reverted several times due to what ultimately turned out
to be incompatibilities in our serialized hash table format.
Several changes went in prior to this to fix those issues since
they were more fundamental and independent of supporting injected
sources, so now that those are fixed this change should hopefully
pass.
llvm-svn: 328363
|
|
When investigating bugs in PDB generation, the first step is
often to do the same link with link.exe and then compare PDBs.
But comparing PDBs is hard because two completely different byte
sequences can both be correct, so it hampers the investigation when
you also have to spend time figuring out not just which bytes are
different, but also if the difference is meaningful.
This patch fixes a couple of cases related to string table emission,
hash table emission, and the order in which we emit strings that
makes more of our bytes the same as the bytes generated by MS PDBs.
Differential Revision: https://reviews.llvm.org/D44810
llvm-svn: 328348
|
|
NFC, this just renames some methods to better express what they
do, and also adds a few helper methods to add some symmetry to the
API in a few places (for example there was a getStringFromId but not
a getIdFromString method in the string table).
llvm-svn: 328221
|
|
The hash table is a list of buckets, and the *value* stored in
the bucket cannot be 0 since that is reserved. However, the code
here was incorrectly skipping over the 0'th bucket entirely.
The 0'th bucket is perfectly fine, just none of these buckets
can contain the value 0.
As a result, whenever there was a string where hash(S) % Size
was equal to 0, we would write the value in the next bucket
instead. We never caught this in our tests due to *another*
bug, which is that we would iterate the entire list of buckets
looking for the value, only using the hash value as a starting
point. However, the real algorithm stops when it finds 0 in
a bucket since it takes that to mean "the item is not in the
hash table".
The unit test is updated to carefully construct a set of hash
values that will cause one item to hash to 0 mod bucket count,
and the reader is also updated to return an error indicating that
the item is not found when it encounters a 0 bucket.
llvm-svn: 328162
|
|
This is still failing on a different bot this time due to some
issue related to hashing absolute paths. Reverting until I can
figure it out.
llvm-svn: 328014
|
|
The issue causing this to fail in certain configurations
should be fixed.
It was due to the fact that DIA apparently expects there to be
a null string at ID 1 in the string table. I'm not sure why this
is important but it seems to make a difference, so set it.
llvm-svn: 328002
|
|
This is causing a test failure on a certain bot, so I'm removing
this temporarily until we can figure out the source of the error.
llvm-svn: 327903
|
|
Natvis is a debug language supported by Visual Studio for
specifying custom visualizers. The /NATVIS option is an
undocumented link.exe flag which will take a .natvis file
and "inject" it into the PDB. This way, you can ship the
debug visualizers for a program along with the PDB, which
is very useful for postmortem debugging.
This is implemented by adding a new "named stream" to the
PDB with a special name of /src/files/<natvis file name>
and simply copying the contents of the xml into this file.
Additionally, we need to emit a single stream named
/src/headerblock which contains a hash table of embedded
files to records describing them.
This patch adds this functionality, including the /NATVIS
option to lld-link.
Differential Revision: https://reviews.llvm.org/D44328
llvm-svn: 327895
|
|
llvm-svn: 320620
|
|
This was originally reverted because of some non-deterministic
failures on certain buildbots. Luckily ASAN eventually caught
this as a stack-use-after-scope, so the fix is included in
this patch.
llvm-svn: 305393
|
|
This is causing failures on linux bots with an invalid stream
read. It doesn't repro in any configuration on Windows, so
reverting until I have a chance to investigate on Linux.
llvm-svn: 305371
|
|
This allows us to use yaml2obj and obj2yaml to round-trip CodeView
symbol and type information without having to manually specify the bytes
of the section. This makes for much easier to maintain tests. See the
tests under lld/COFF in this patch for example. Before they just said
SectionData: <blob> whereas now we can use meaningful record
descriptions. Note that it still supports the SectionData yaml field,
which could be useful for initializing a section to invalid bytes for
testing, for example.
Differential Revision: https://reviews.llvm.org/D34127
llvm-svn: 305366
|
|
This was reverted due to a "missing" file, but in reality
what happened was that I renamed a file, and then due to
a merge conflict both the old file and the new file got
added to the repository. This led to an unused cpp file
being in the repo and not referenced by any CMakeLists.txt
but #including a .h file that wasn't in the repo. In an
even more unfortunate coincidence, CMake didn't report the
unused cpp file because it was in a subdirectory of the
folder with the CMakeLists.txt, and not in the same directory
as any CMakeLists.txt.
The presence of the unused file was then breaking certain
tools that determine file lists by globbing rather than
by what's specified in CMakeLists.txt
In any case, the fix is to just remove the unused file from
the patch set.
llvm-svn: 302042
|
|
The patch is failing to add StringTableStreamBuilder.h, but that isn't
even discovered because the corresponding StringTableStreamBuilder.cpp
isn't added to any CMakeLists.txt file and thus never built. I think
this patch is just incomplete.
llvm-svn: 302002
|
|
Previously we had knowledge of how to serialize and deserialize
a string table inside of DebugInfo/PDB, but the string table
that it serializes contains a piece that is actually considered
CodeView and can appear outside of a PDB. We already have logic
in llvm-readobj and MCCodeView to read and write this format,
so it doesn't make sense to duplicate the logic in DebugInfoPDB
as well.
This patch makes codeview::StringTable (for writing) and
codeview::StringTableRef (for reading), updates DebugInfoPDB
to use these classes for its own writing, and updates llvm-readobj
to additionally use StringTableRef for reading.
It's a bit more difficult to get MCCodeView to use this for
writing, but it's a logical next step.
llvm-svn: 301986
|
|
With the forthcoming codeview::StringTable which a pdb::StringTable
would hold an instance of as one member, this ambiguity becomes
confusing. Rename to PDBStringTable to avoid this.
llvm-svn: 301948
|
