<feed xmlns='http://www.w3.org/2005/Atom'>
<title>llvm-project.git/llvm/lib/DebugInfo/PDB/Native/PDBStringTableBuilder.cpp, branch users/nico/python-2</title>
<subtitle>Unnamed repository; edit this file 'description' to name the repository.
</subtitle>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/'/>
<entry>
<title>[LLD][COFF] Add support for `--time-trace` (#68236)</title>
<updated>2023-10-06T02:33:58+00:00</updated>
<author>
<name>Alexandre Ganea</name>
<email>37383324+aganea@users.noreply.github.com</email>
</author>
<published>2023-10-06T02:33:58+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=356139bd027d65b6843cbd4eda642104cfe6cf8f'/>
<id>356139bd027d65b6843cbd4eda642104cfe6cf8f</id>
<content type='text'>
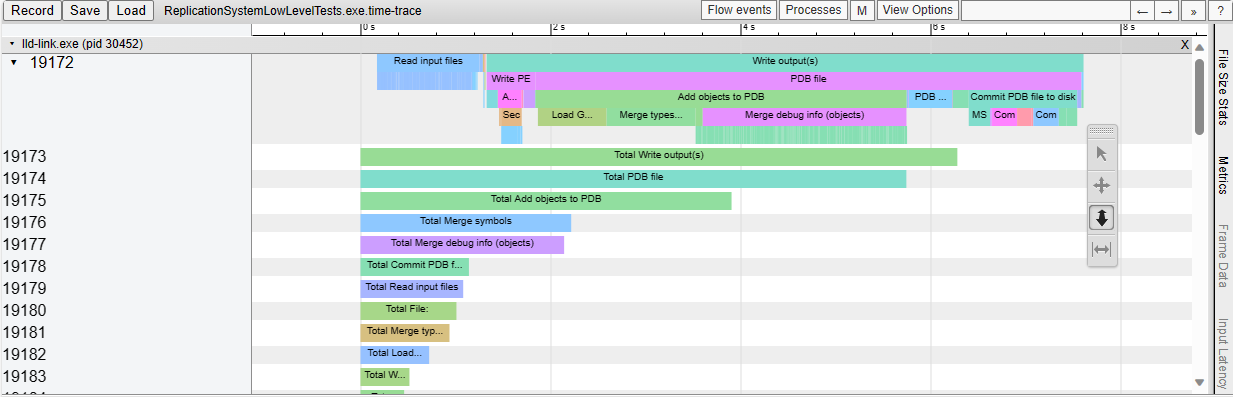
This adds support for generating Chrome-tracing .json profile traces in
the LLD COFF driver.

Also add the necessary time scopes, so that the profile trace shows in
great detail which tasks are executed.

As an example, this is what we see when linking a Unreal Engine
executable:

![image](https://github.com/llvm/llvm-project/assets/37383324/b2e26eb4-9d37-4cf9-b002-48b604e7dcb7)</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
This adds support for generating Chrome-tracing .json profile traces in
the LLD COFF driver.

Also add the necessary time scopes, so that the profile trace shows in
great detail which tasks are executed.

As an example, this is what we see when linking a Unreal Engine
executable:

![image](https://github.com/llvm/llvm-project/assets/37383324/b2e26eb4-9d37-4cf9-b002-48b604e7dcb7)</pre>
</div>
</content>
</entry>
<entry>
<title>[llvm] Qualify auto (NFC)</title>
<updated>2022-08-08T06:55:27+00:00</updated>
<author>
<name>Kazu Hirata</name>
<email>kazu@google.com</email>
</author>
<published>2022-08-08T06:55:27+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=e20d210eef92f3952de0e89ef2f01a146480a13b'/>
<id>e20d210eef92f3952de0e89ef2f01a146480a13b</id>
<content type='text'>
Identified with readability-qualified-auto.
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
Identified with readability-qualified-auto.
</pre>
</div>
</content>
</entry>
<entry>
<title>Drop some more global std::maps. NFCI.</title>
<updated>2022-03-06T12:28:29+00:00</updated>
<author>
<name>Benjamin Kramer</name>
<email>benny.kra@googlemail.com</email>
</author>
<published>2022-03-06T12:24:42+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=fbce4a78035c32792b0a13cf1f169048b822c06b'/>
<id>fbce4a78035c32792b0a13cf1f169048b822c06b</id>
<content type='text'>
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
</pre>
</div>
</content>
</entry>
<entry>
<title>Expand comment about how StringsToBuckets was computed, and add more entries</title>
<updated>2019-07-15T18:56:56+00:00</updated>
<author>
<name>Nico Weber</name>
<email>nicolasweber@gmx.de</email>
</author>
<published>2019-07-15T18:56:56+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=ac6375d99d19e2c8c53dc72caa457833f6fa6641'/>
<id>ac6375d99d19e2c8c53dc72caa457833f6fa6641</id>
<content type='text'>
The construction was explained in
https://reviews.llvm.org/D44810?id=139526#inline-391999 but reading the code
shouldn't require hunting down old reviews to understand it.

The precomputed list was missing an entry for the empty list case, and
one entry at the very end. (The current last entry is the last one where
3 * BucketCount fits in a signed int, but the reference implementation
uses unsigneds as far as I can tell, so there's room for one more entry.)

No behavior change for inputs seen in practice.

Differential Revision: https://reviews.llvm.org/D64738

llvm-svn: 366107
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
The construction was explained in
https://reviews.llvm.org/D44810?id=139526#inline-391999 but reading the code
shouldn't require hunting down old reviews to understand it.

The precomputed list was missing an entry for the empty list case, and
one entry at the very end. (The current last entry is the last one where
3 * BucketCount fits in a signed int, but the reference implementation
uses unsigneds as far as I can tell, so there's room for one more entry.)

No behavior change for inputs seen in practice.

Differential Revision: https://reviews.llvm.org/D64738

llvm-svn: 366107
</pre>
</div>
</content>
</entry>
<entry>
<title>[PDB] Fix hash function used to write /src/headerblock</title>
<updated>2019-04-29T23:09:35+00:00</updated>
<author>
<name>Nico Weber</name>
<email>nicolasweber@gmx.de</email>
</author>
<published>2019-04-29T23:09:35+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=e577be4ed1ecb7e354ec25f431de058365befe16'/>
<id>e577be4ed1ecb7e354ec25f431de058365befe16</id>
<content type='text'>
lld-link used to write PDB files that DIA couldn't recover natvis
files from if:

- The global strings table was &gt; 64kiB
- There were at least 3 natvis files

The cause was that the hash function for the /src/headerblock stream
was incorrect: It needs to be truncated to 16 bit.

If the global strings table was &lt;= 64kiB, truncating to 16 bit is a
no-op, so this wasn't needed for small programs.

If there are only 1 or 2 natvis files, then the growth strategy in
HashTable::grow() would mean the hash table would have 2 buckets (for 1
natvis file) or 4 buckets (for 4 natvis files), and since the hash
function is used modulo number of buckets, and since 2 and 4 divide
0x10000, the missing `% 0x10000` is a no-op there too. For 3 natvis
files, the hash table grows to 6 buckets, which has a factor that's not
common with 0x10000 and the difference starts to matter.

Fixes PR41626.

Differential Revision: https://reviews.llvm.org/D61277

llvm-svn: 359515
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
lld-link used to write PDB files that DIA couldn't recover natvis
files from if:

- The global strings table was &gt; 64kiB
- There were at least 3 natvis files

The cause was that the hash function for the /src/headerblock stream
was incorrect: It needs to be truncated to 16 bit.

If the global strings table was &lt;= 64kiB, truncating to 16 bit is a
no-op, so this wasn't needed for small programs.

If there are only 1 or 2 natvis files, then the growth strategy in
HashTable::grow() would mean the hash table would have 2 buckets (for 1
natvis file) or 4 buckets (for 4 natvis files), and since the hash
function is used modulo number of buckets, and since 2 and 4 divide
0x10000, the missing `% 0x10000` is a no-op there too. For 3 natvis
files, the hash table grows to 6 buckets, which has a factor that's not
common with 0x10000 and the difference starts to matter.

Fixes PR41626.

Differential Revision: https://reviews.llvm.org/D61277

llvm-svn: 359515
</pre>
</div>
</content>
</entry>
<entry>
<title>Delay initialization of three static global maps, NFC</title>
<updated>2019-03-28T17:33:41+00:00</updated>
<author>
<name>Reid Kleckner</name>
<email>rnk@google.com</email>
</author>
<published>2019-03-28T17:33:41+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=85e2cdac7367328e384cdbfed00928a43ae66034'/>
<id>85e2cdac7367328e384cdbfed00928a43ae66034</id>
<content type='text'>
This avoids allocating a few KB of heap memory on startup, and instead
allocates these maps lazily. I noticed this while profiling LLD.

llvm-svn: 357192
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
This avoids allocating a few KB of heap memory on startup, and instead
allocates these maps lazily. I noticed this while profiling LLD.

llvm-svn: 357192
</pre>
</div>
</content>
</entry>
<entry>
<title>Update the file headers across all of the LLVM projects in the monorepo</title>
<updated>2019-01-19T08:50:56+00:00</updated>
<author>
<name>Chandler Carruth</name>
<email>chandlerc@gmail.com</email>
</author>
<published>2019-01-19T08:50:56+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=2946cd701067404b99c39fb29dc9c74bd7193eb3'/>
<id>2946cd701067404b99c39fb29dc9c74bd7193eb3</id>
<content type='text'>
to reflect the new license.

We understand that people may be surprised that we're moving the header
entirely to discuss the new license. We checked this carefully with the
Foundation's lawyer and we believe this is the correct approach.

Essentially, all code in the project is now made available by the LLVM
project under our new license, so you will see that the license headers
include that license only. Some of our contributors have contributed
code under our old license, and accordingly, we have retained a copy of
our old license notice in the top-level files in each project and
repository.

llvm-svn: 351636
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
to reflect the new license.

We understand that people may be surprised that we're moving the header
entirely to discuss the new license. We checked this carefully with the
Foundation's lawyer and we believe this is the correct approach.

Essentially, all code in the project is now made available by the LLVM
project under our new license, so you will see that the license headers
include that license only. Some of our contributors have contributed
code under our old license, and accordingly, we have retained a copy of
our old license notice in the top-level files in each project and
repository.

llvm-svn: 351636
</pre>
</div>
</content>
</entry>
<entry>
<title>[PDB] Resubmit "Support embedding natvis files in PDBs."</title>
<updated>2018-03-23T19:57:25+00:00</updated>
<author>
<name>Zachary Turner</name>
<email>zturner@google.com</email>
</author>
<published>2018-03-23T19:57:25+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=f228276262af761d3061e40251d48efa49408397'/>
<id>f228276262af761d3061e40251d48efa49408397</id>
<content type='text'>
This was reverted several times due to what ultimately turned out
to be incompatibilities in our serialized hash table format.

Several changes went in prior to this to fix those issues since
they were more fundamental and independent of supporting injected
sources, so now that those are fixed this change should hopefully
pass.

llvm-svn: 328363
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
This was reverted several times due to what ultimately turned out
to be incompatibilities in our serialized hash table format.

Several changes went in prior to this to fix those issues since
they were more fundamental and independent of supporting injected
sources, so now that those are fixed this change should hopefully
pass.

llvm-svn: 328363
</pre>
</div>
</content>
</entry>
<entry>
<title>[PDB] Make our PDBs look more like MS PDBs.</title>
<updated>2018-03-23T18:43:39+00:00</updated>
<author>
<name>Zachary Turner</name>
<email>zturner@google.com</email>
</author>
<published>2018-03-23T18:43:39+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=a6fb536e5b5c98d3ca46fbd7ea21893f633d21d8'/>
<id>a6fb536e5b5c98d3ca46fbd7ea21893f633d21d8</id>
<content type='text'>
When investigating bugs in PDB generation, the first step is
often to do the same link with link.exe and then compare PDBs.

But comparing PDBs is hard because two completely different byte
sequences can both be correct, so it hampers the investigation when
you also have to spend time figuring out not just which bytes are
different, but also if the difference is meaningful.

This patch fixes a couple of cases related to string table emission,
hash table emission, and the order in which we emit strings that
makes more of our bytes the same as the bytes generated by MS PDBs.

Differential Revision: https://reviews.llvm.org/D44810

llvm-svn: 328348
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
When investigating bugs in PDB generation, the first step is
often to do the same link with link.exe and then compare PDBs.

But comparing PDBs is hard because two completely different byte
sequences can both be correct, so it hampers the investigation when
you also have to spend time figuring out not just which bytes are
different, but also if the difference is meaningful.

This patch fixes a couple of cases related to string table emission,
hash table emission, and the order in which we emit strings that
makes more of our bytes the same as the bytes generated by MS PDBs.

Differential Revision: https://reviews.llvm.org/D44810

llvm-svn: 328348
</pre>
</div>
</content>
</entry>
<entry>
<title>[Codeview/PDB] Rename some methods for clarity.</title>
<updated>2018-03-22T17:37:28+00:00</updated>
<author>
<name>Zachary Turner</name>
<email>zturner@google.com</email>
</author>
<published>2018-03-22T17:37:28+00:00</published>
<link rel='alternate' type='text/html' href='https://git.belthelziquor.com/llvm-project.git/commit/?id=71d36ad9f919d420beed28f6467123acb621f486'/>
<id>71d36ad9f919d420beed28f6467123acb621f486</id>
<content type='text'>
NFC, this just renames some methods to better express what they
do, and also adds a few helper methods to add some symmetry to the
API in a few places (for example there was a getStringFromId but not
a getIdFromString method in the string table).

llvm-svn: 328221
</content>
<content type='xhtml'>
<div xmlns='http://www.w3.org/1999/xhtml'>
<pre>
NFC, this just renames some methods to better express what they
do, and also adds a few helper methods to add some symmetry to the
API in a few places (for example there was a getStringFromId but not
a getIdFromString method in the string table).

llvm-svn: 328221
</pre>
</div>
</content>
</entry>
</feed>
